The Science that powers fair, skills-first hiring
Intelligent automation and science-backed assessments working together to elevate the pre-hire process with speed, fairness, and consistency. Our models are designed and continuously validated by our in-house science team to support decisions that are reliable, transparent, and evidence-based.
Meet the people behind the Science
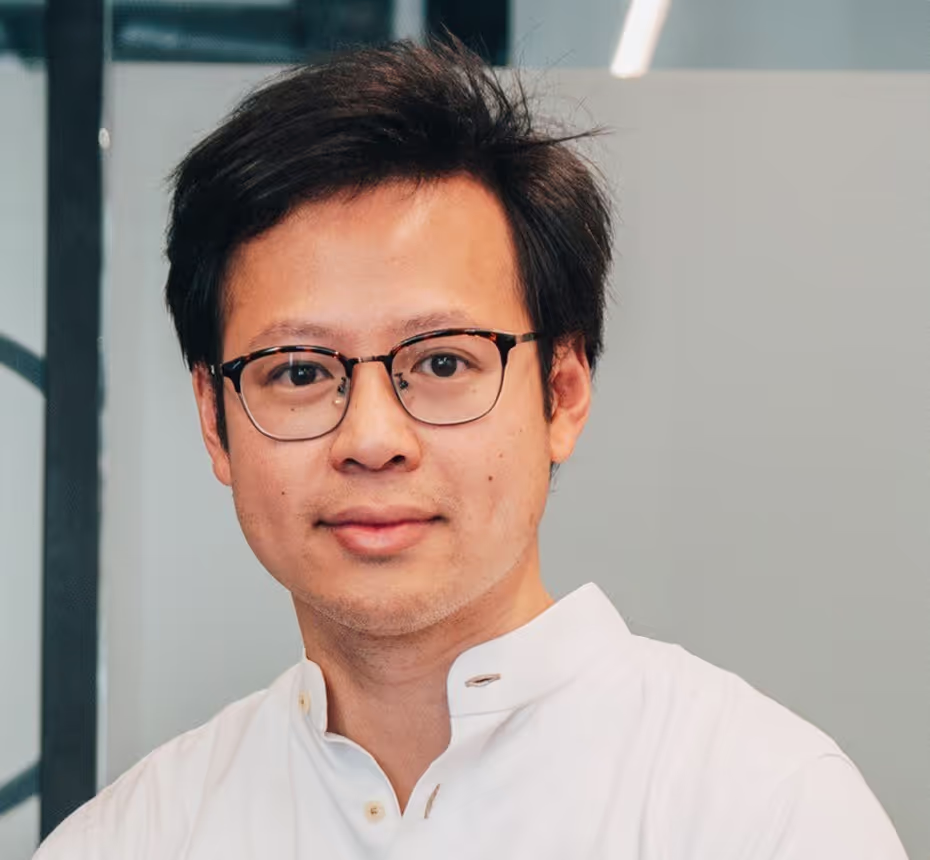
Dr. Aiden Loe
Head of Science
As Head of Science, Aiden leads Maki’s scientific vision, ensuring that every AI-driven assessment is grounded in psychometric rigor, ethical AI principles, and empirical validation.
He oversees the research and development of Maki’s AI assessment models, guiding the intersection of computational psychology, machine learning, and human behavior.
Bridging psychology, data science, and ethical AI to make hiring both scientific and human
His research has been published in leading journals and proceedings, including Nature Scientific Reports, The Lancet (Public Health, Psychiatry), Psychological Medicine, AAAI, IJCAI, and Philosophy and Theory of Artificial Intelligence. With 50+ peer-reviewed papers and 5,000+ citations, his work bridges the gap between academic excellence and real-world application in HR technology.
Former roles
Lead Psychometrician (Cambridge Psychometrics Centre), Visiting Lecturer (University of Cambridge), Academic Collaborator (University of Oxford)
Education
PhD in Psychology, University of Cambridge, MSc in Psychometrics & Social Psychology
Awards
UK Psychometrics Forum Excellence in Psychometrics Award (2017); John B. Carroll Award (2016)
Team members
Behind every assessment, model, and validation loop stands Maki’s dedicated Science Team: together, they design assessments, ensure psychometric rigor, and monitor fairness and validity across every new product release.
The rationale behind Maki’s approach
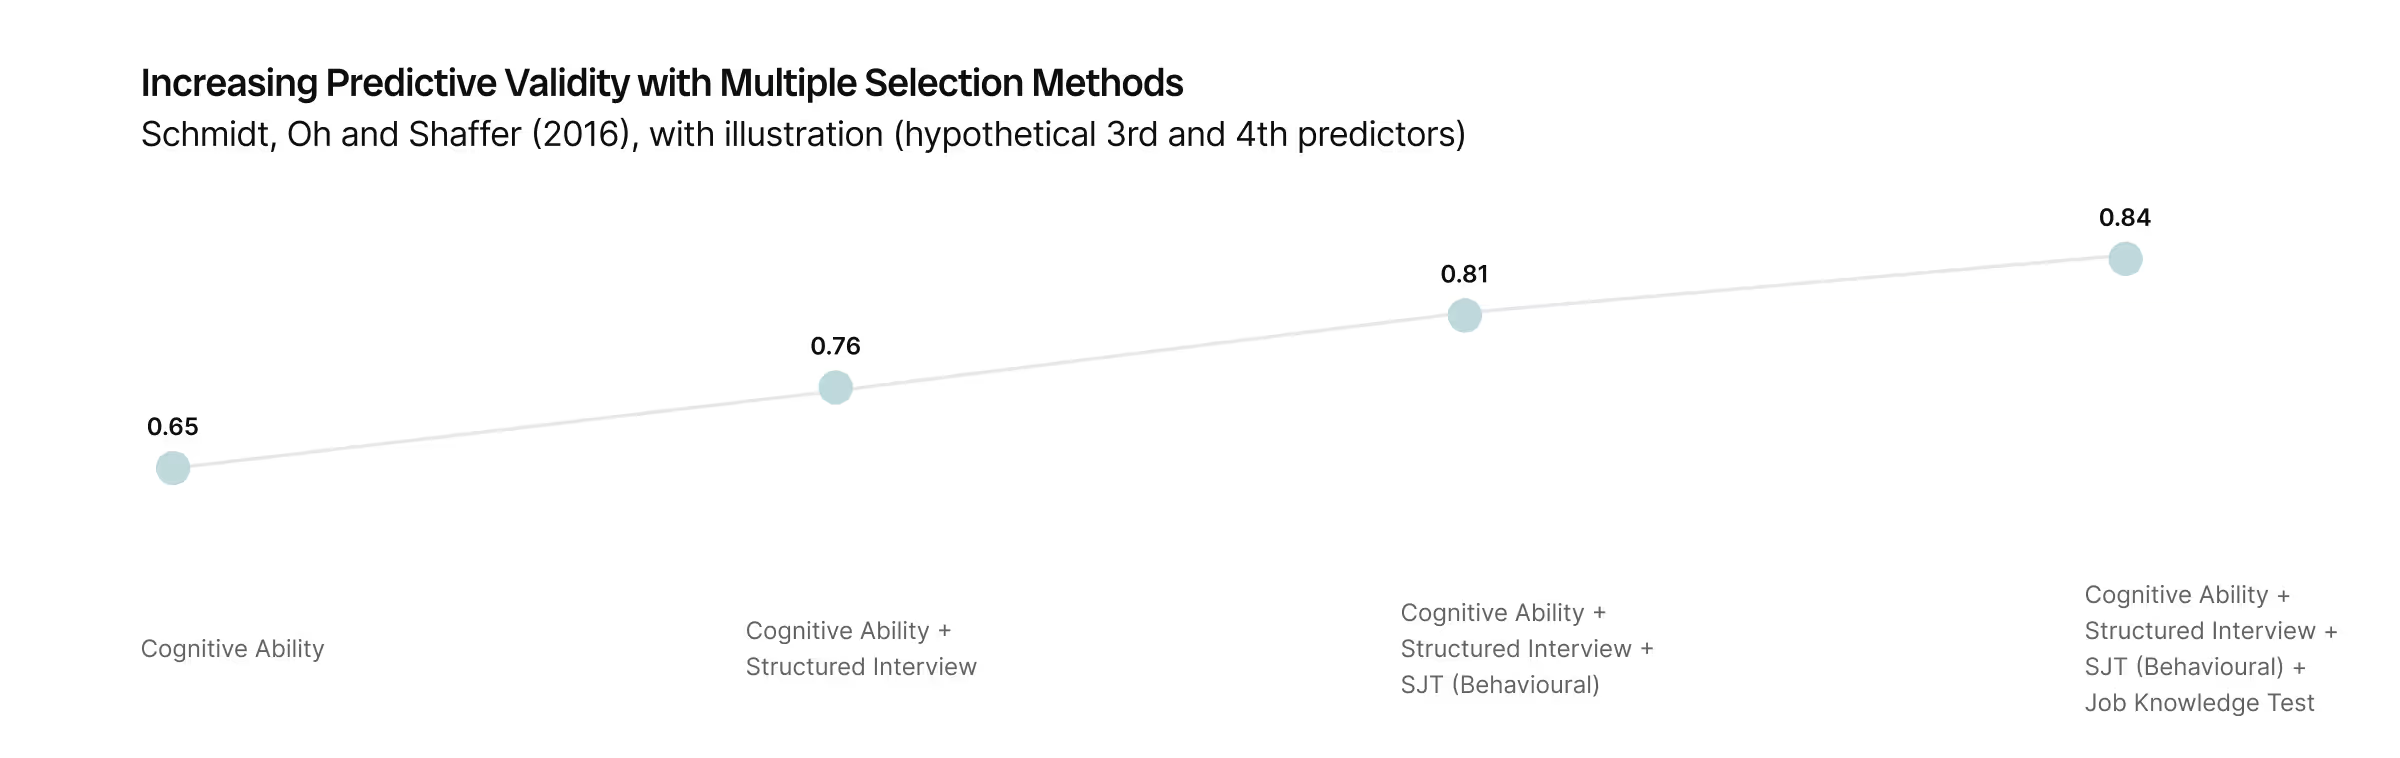
Recent Research has shown that the most predictive and equitable selection methods are job-specific and behaviorally grounded, such as structured interviews and situational judgement tests
Personality traits alone provide limited predictive validity for overall job performance outcomes
Composite behavioral measures achieve similar validity to standalone ability tests, with much smaller group differences
Real responses to realistic challenges outperform abstract reasoning or trait self-reports
That’s why Maki builds AI-scored, psychometrically robust assessments grounded in real behavior and data, to make hiring decisions that are both predictive and fairer
Skills-first hiring, made immersive
We leverage a combination of human expertise and LLMs to create and evaluate 300+ skills
We assess soft and behavioral skills, cognitive aptitude, coding, job-specific knowledge, and written & spoken language proficiency. Language proficiency assessments are the only assessments in which spoken delivery itself is scored, because it is the skill being measured. All other assessments are scored on the content of the response.
Our assessments span multiple formats, including immersive tasks, conversational interactions, situational judgement tests (SJTs), free-text responses (written or spoken), and audio/video questions
We support practical “knock-out” questions such as availability, location, and salary expectations

A 12-step science-backed process
This process applies to Maki's assessment library. Conversational interview scoring follows the LLM evaluation loop described further down this page.
Scoring like human experts: audited, validated, and at global scale
Language proficiency assessments
Written and spoken proficiency in 20+ languages, aligned to IELTS/CEFR and calibrated with psychometric models. Pronunciation, fluency, rhythm and clarity are scored here.
Interview and behavioral scoring
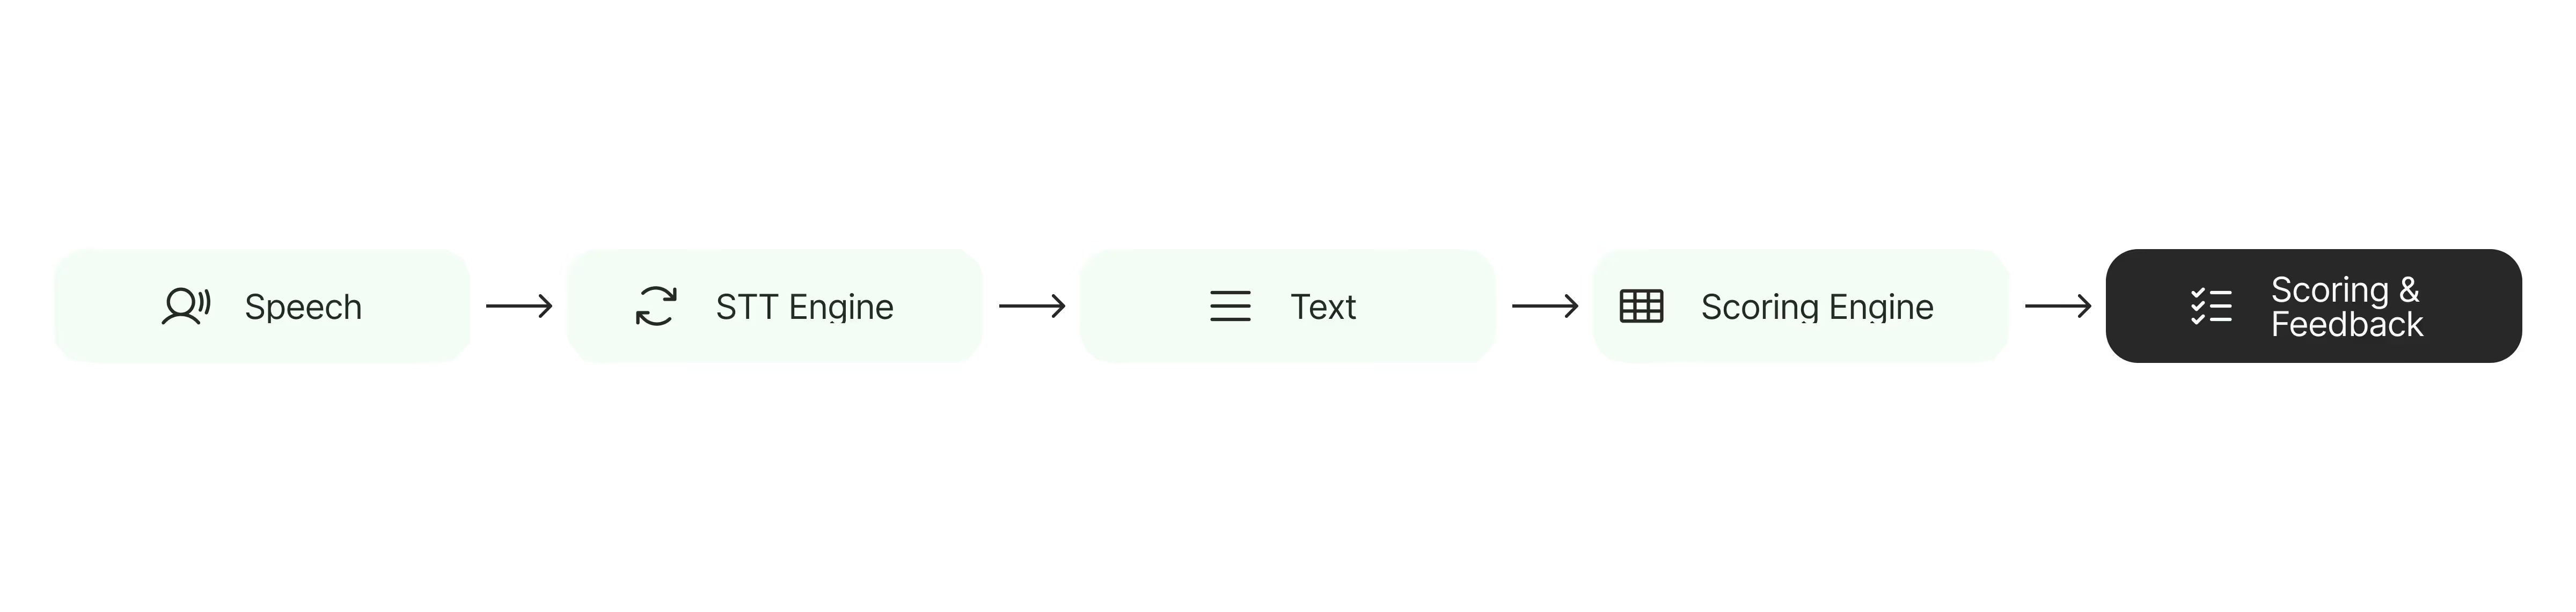
Scored on the content of the response against a defined rubric. Delivery, pace, accent and speech patterns are not scored.
Transcription
Speech is transcribed before scoring. Transcription accuracy is benchmarked using WER, CER, BLEU and multilingual metrics across supported languages.

We are relentless about raising the quality of our assessments
Our commitment to science does not stop at deployment. Maki’s in-house Science team continuously collects and analyzes performance data to ensure assessments remain accurate, fair, and predictive over time.
We run ongoing psychometric analyses to strengthen reliability, validity, and relevance, including checks on internal consistency, content coverage, fairness metrics, and predictive performance.
This continuous work helps us refine each assessment so it reflects real job success, reduces unwanted bias, and supports confident decisions at scale.
Consistent, transparent, and legally defensible
Structured open-ended answers are scored with BARS (Behaviorally Anchored Rating Scales) for each competency
Ensures consistent, objective, transparent scoring
Built to support clients' obligations under UGESP, Title VII and the Equality Act
AI-scored open-ended items are benchmarked against human raters with ICC, ANOVA, Bland–Altman, and Welch methods


Adding new languages in weeks, not months
Double-blind translations
Double-blind translations by certified agencies
Advanced review
Native speaker review & psychometric consistency checks
Fast process
2–4 weeks to add a new language
Multilingual
Already available in 40+ languages

Designed for inclusive hiring from day one
What we test
Job-relevant, objective assessments, designed and reviewed to minimise cultural loading
Differential Item Functioning (DIF) analysis at build time, and adverse impact monitoring (80% rule) across gender, age and nationality where sample sizes support it
How we design
Clear instructions, practice opportunities and simple language
Available in 40+ languages, with support for non-native speakers
Configurable accommodations: flexible timing and alternative formats, no proof required
Combining psychometrics & machine-learning evaluations
Assessments in our library are validated using IRT modeling, reliability checks, and predictive validity studies
AI scoring is benchmarked against expert human ratings to ensure accuracy, fairness, and real-world alignment
Continuous monitoring uses ML techniques such as drift detection, bias analysis, and performance audits to maintain scoring that is scientifically robust and trustworthy

Always-on governance
We evaluate LLMs with a 10-step loop
Transparency supports better decision-making
Hiring decisions carry real consequences. That’s why we design our systems to make scoring criteria, model behavior, and evaluation steps as clear and reviewable as possible, helping organizations understand how results are produced.
Structured, rubric-based scoring using LLMs
Our AI agents follow clearly defined scoring criteria. Every result is grounded in observable features and rubric-based indicators, allowing stakeholders to understand how scores are derived without relying on black-box reasoning.
Scientific rigor, not shortcuts
Developed by psychometricians and reviewed against recognised standards for assessment quality, including ISO 10667 and the AERA/APA/NCME Standards for Educational and Psychological Testing. Our AEDT agents were independently audited by Holistic AI under NYC LL144 in 2026. We measure validity, bias and impact, and monitor for drift.
Compliant by default
NYC Local Law 144: our AEDT agents were independently audited by Holistic AI. GDPR: compliant, with EU data residency and candidate data rights built into the platform. EU AI Act: our conformity assessment is being finalised with an external partner. We will publish the outcome.
Enterprise-Grade Infrastructure
Maki’s infrastructure is ISO 27001 certified, built on Google Cloud Platform with AES-256 encryption, TLS-secured data transmission, and redundant storage in Belgium, France, and Germany.
Privacy-first by architecture
Candidates own their data. Maki enforces data minimization and automated deletion policies to honor the right to be forgotten under GDPRtech.
Built-in fairness monitoring
Assessments undergo Differential Item Functioning (DIF) analysis before launch. In live deployments, adverse impact is monitored across gender, age and nationality, where sample sizes support reliable analysis. See Scope and limitations below for what this does not currently cover.